If your team collects data from public websites, the AI crawler rules that decide what your collectors can reach changed on 15 September 2026. Cloudflare now sorts automated visitors into three behaviour categories, and it has given site owners a way to block AI training while staying visible in search. If any of your sources sit behind Cloudflare, this reaches them. Your collector is not a search engine and it is not a person, so it now has to answer a question it never had to answer before: which category does it belong to, and can it say so honestly?
What the new AI crawler rules changed on 15 September 2026
Cloudflare published the change on 15 September 2026, in a post called "Have it both ways: stay discoverable in search while disallowing AI training". Three things landed at once. Cloudflare says it now separates bot behaviour into three categories: Search, Training and Agent. It added a setting called Disallow AI Training, which lets a site block the use of its content for training AI models while staying visible in search. And from that date, according to Cloudflare, new domains joining the network get preset configurations based on their monetisation model, with ad-supported sites defaulting to Disallow AI Training.
None of that is a ban on collecting data. It is a change in how a site owner states what it wants, and in what a network in front of that site can act on. The practical effect for you is that the question has moved. It used to be how fast you crawl. Now it is also what you are crawling for.
Search, Training and Agent are now three different questions
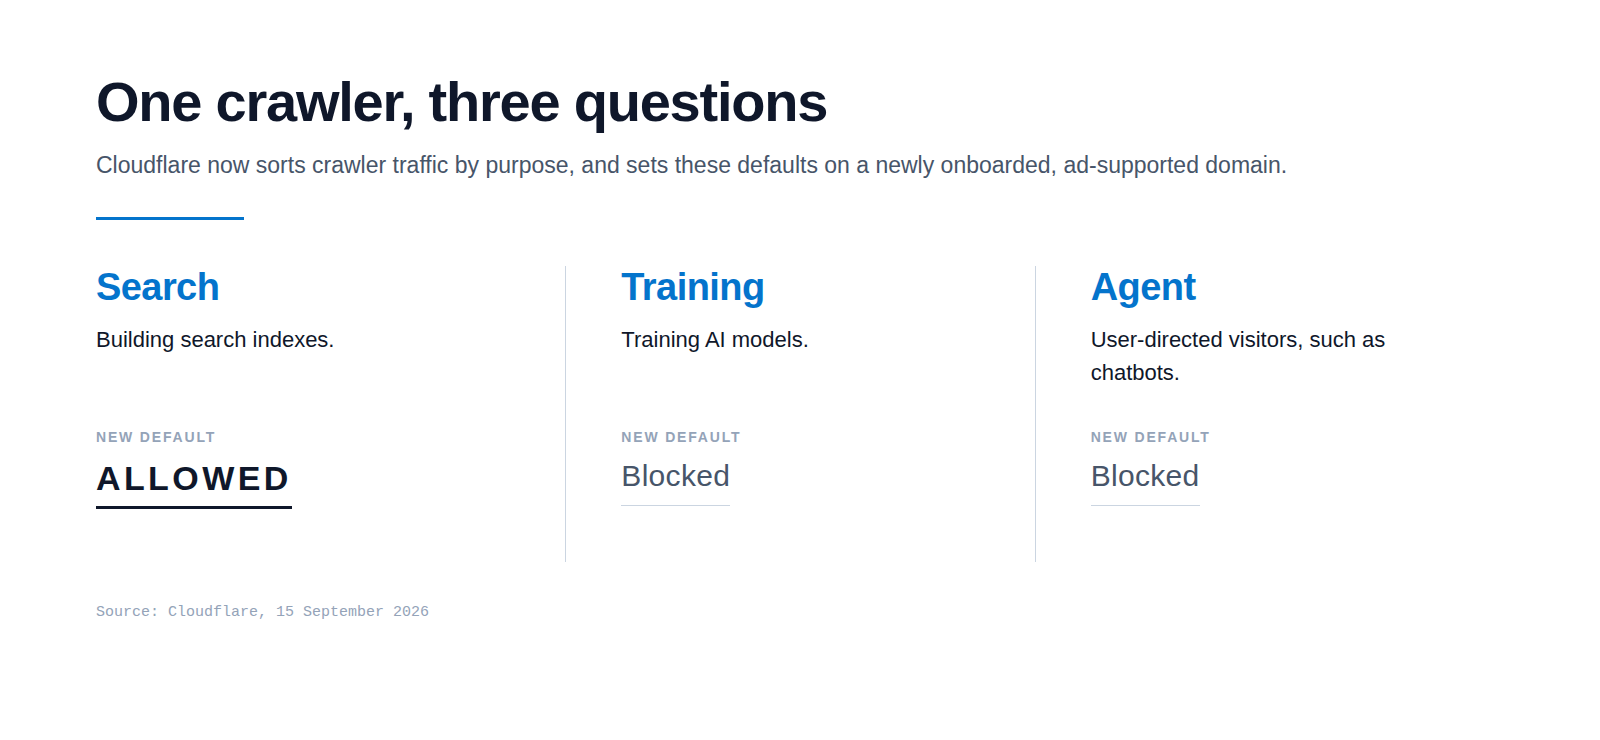
Cloudflare defines the three categories by behaviour. Search is building a search index. Training is training AI models. Agent is a user-directed visitor, such as a chatbot fetching a page because a person asked it to. A single operator can do more than one of these, which is the point of splitting them: a site owner can say yes to one and no to another. Cloudflare says that for a newly onboarded domain that displays ads, the defaults are Search allowed, AI training disallowed, and Agent blocked on pages with ads.
Here is the awkward part for a business collector. A pipeline that pulls listings into a dashboard is not building a public search index. It is usually not training a model either. And it is not a person clicking a link. So it does not sit cleanly in any of the three. If you leave that ambiguity for someone else to resolve, your collector risks being read as the least welcome option available rather than the one you would have chosen. If you cannot describe your collector in the site owner's language, someone else will pick the label for you.